Resume example
Data Scientist resume example
By the Resumade team · About our content
A Data Scientist resume must clear automated keyword filters and then prove to a hiring manager that you ship models that move business metrics. This example does both: it leads with quantified impact, clusters tools for ATS scanners, and tells a coherent story of growing ML ownership.
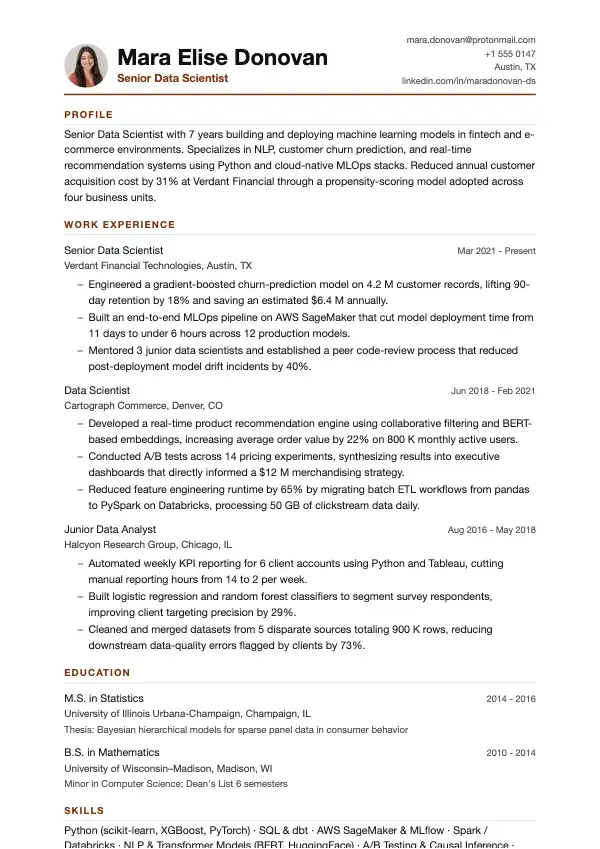
Template: Meridian
Read this resume as text
Mara Elise Donovan
Senior Data Scientist
mara.donovan@protonmail.com · +1 555 0147 · Austin, TX · linkedin.com/in/maradonovan-ds
- Profile
- Senior Data Scientist with 7 years building and deploying machine learning models in fintech and e-commerce environments. Specializes in NLP, customer churn prediction, and real-time recommendation systems using Python and cloud-native MLOps stacks. Reduced annual customer acquisition cost by 31% at Verdant Financial through a propensity-scoring model adopted across four business units.
- Work Experience
Senior Data Scientist
Verdant Financial Technologies, Austin, TX · Mar 2021 - Present
- Engineered a gradient-boosted churn-prediction model on 4.2 M customer records, lifting 90-day retention by 18% and saving an estimated $6.4 M annually.
- Built an end-to-end MLOps pipeline on AWS SageMaker that cut model deployment time from 11 days to under 6 hours across 12 production models.
- Mentored 3 junior data scientists and established a peer code-review process that reduced post-deployment model drift incidents by 40%.
Data Scientist
Cartograph Commerce, Denver, CO · Jun 2018 - Feb 2021
- Developed a real-time product recommendation engine using collaborative filtering and BERT-based embeddings, increasing average order value by 22% on 800 K monthly active users.
- Conducted A/B tests across 14 pricing experiments, synthesizing results into executive dashboards that directly informed a $12 M merchandising strategy.
- Reduced feature engineering runtime by 65% by migrating batch ETL workflows from pandas to PySpark on Databricks, processing 50 GB of clickstream data daily.
Junior Data Analyst
Halcyon Research Group, Chicago, IL · Aug 2016 - May 2018
- Automated weekly KPI reporting for 6 client accounts using Python and Tableau, cutting manual reporting hours from 14 to 2 per week.
- Built logistic regression and random forest classifiers to segment survey respondents, improving client targeting precision by 29%.
- Cleaned and merged datasets from 5 disparate sources totaling 900 K rows, reducing downstream data-quality errors flagged by clients by 73%.
- Education
M.S. in Statistics
University of Illinois Urbana-Champaign, Champaign, IL · 2014 - 2016
Thesis: Bayesian hierarchical models for sparse panel data in consumer behavior
B.S. in Mathematics
University of Wisconsin–Madison, Madison, WI · 2010 - 2014
Minor in Computer Science; Dean's List 6 semesters
- Skills
- Python (scikit-learn, XGBoost, PyTorch) · SQL & dbt · AWS SageMaker & MLflow · Spark / Databricks · NLP & Transformer Models (BERT, HuggingFace) · A/B Testing & Causal Inference · Tableau & Looker · Feature Engineering & Data Pipelines · AWS Certified Machine Learning – Specialty (2022)
- Links
- Portfolio: maradonovan.io · GitHub: github.com/mara-donovan · LinkedIn: linkedin.com/in/maradonovan-ds
What makes this resume work
- Every bullet opens with a strong action verb and closes with a specific number — retention rate, dollar savings, or time reduction — so hiring managers can instantly gauge scale and impact without reading between the lines.
- The skills section groups languages, platforms, and certifications into recognizable tool names (e.g., 'AWS SageMaker & MLflow') rather than vague categories, matching the exact strings recruiters type into applicant-tracking systems.
- The summary names seniority level, years of experience, two domain specialisms, and one headline result in three sentences, giving a recruiter everything needed to shortlist at a glance.
- The career arc moves logically from analyst to data scientist to senior data scientist, with each role showing expanded scope — from automating reports to owning production ML pipelines — which signals genuine progression rather than lateral movement.
Keywords that help you pass the ATS
Work the ones that fit your experience into your resume, naturally, not stuffed.
How to write a Data Scientist resume
Choose the right format for a Data Scientist resume
Use a reverse-chronological format unless you are making a significant career pivot. Recruiters spend about seven seconds on an initial scan (Ladders eye-tracking study, 2018), so your most recent and relevant work must appear above the fold. Keep the document to one page if you have fewer than eight years of experience; two pages are acceptable beyond that.
Stick to a single-column layout with clear section headers. ATS systems at companies like Amazon, Meta, and large financial institutions often misparse multi-column tables and text boxes, causing your skills and job titles to drop out entirely. Use a standard font such as Calibri or Georgia at 10–12 pt, and save the file as a PDF unless the job posting specifically requests a .docx.
- Margins: 0.5–1 inch on all sides
- Section order: Contact → Summary → Experience → Skills → Education → Certifications
- File name: FirstLast_DataScientist_Resume.pdf
- No photos, no headshots, no icons that confuse ATS parsers
Write a professional summary that earns a second look
Your summary is three to four sentences that answer one question: why should this team hire you over the other 300 applicants? Name your years of experience, your core technical domain (NLP, computer vision, causal inference, time-series forecasting, etc.), the business impact you have driven, and the industry you know best. Skip phrases like 'passionate data professional' — they mean nothing.
Example: "Data Scientist with 6 years of experience building production-grade machine learning models in the e-commerce and fintech sectors. Specialized in gradient-boosted tree ensembles and survival analysis, with a track record of reducing customer churn by double digits and improving revenue forecasting accuracy to within 3% of actuals. Proficient in Python, Spark, and dbt; experienced presenting model outputs to C-suite stakeholders and translating findings into actionable product decisions."
Write work-experience bullets that show business impact
Each bullet should follow a tight action → method → result structure. Quantify everything you can: percentage improvements, dollar values, processing time reductions, model accuracy gains, or user counts affected. Avoid vague verbs like 'assisted with' or 'helped develop.' Own the work.
Recruiters at data-heavy companies — banks, healthcare systems, SaaS platforms — want to see that your models shipped and that someone cared about the output. If a model never reached production, say what stage it reached and why it mattered analytically.
- Built an XGBoost churn-prediction model trained on 18 months of clickstream data, achieving an AUC of 0.91 and enabling the retention team to reduce monthly churn by 14%, saving an estimated $2.3M annually.
- Redesigned the ETL pipeline for daily sales forecasting using Apache Spark and Airflow, cutting data processing time from 4 hours to 22 minutes and eliminating a recurring Monday-morning reporting delay that had persisted for two years.
Skills and certifications recruiters and ATS systems look for
List skills in a dedicated section using exact terminology from job postings, because ATS systems match on string literals. Separate languages, libraries, platforms, and statistical methods into labeled sub-groups so a recruiter can find what they need at a glance. Do not list every tool you have ever touched — prioritize depth over breadth.
Certifications add credibility, especially for candidates without a graduate degree or for those moving from academia to industry. The most recognized credentials in this field right now are the AWS Certified Machine Learning – Specialty, Google Professional Machine Learning Engineer, Databricks Certified Associate Developer for Apache Spark, and the Coursera/DeepLearning.AI Deep Learning Specialization. List the issuing body and the year earned.
- Languages: Python (pandas, scikit-learn, PyTorch, statsmodels), R, SQL
- Platforms: AWS SageMaker, Google Vertex AI, Databricks, Snowflake, dbt
- Methods: A/B testing, causal inference, time-series forecasting, NLP, survival analysis
- Visualization: Tableau, Looker, Matplotlib, Plotly
- Version control and workflow: Git, MLflow, Docker, Airflow
Education, licenses, and extras that close the deal
List your highest degree first: degree name, institution, and graduation year. A master's or PhD in Statistics, Computer Science, Applied Mathematics, or a related quantitative field is common in this role, but it is not a universal requirement — your project portfolio and certifications can compensate. If your GPA was 3.5 or above and you graduated within the last five years, include it.
Add a GitHub URL or portfolio link in your contact header if your repositories contain documented, well-commented projects with README files explaining the business problem, dataset, methodology, and results. Kaggle rankings (Expert and above) are worth a single line under certifications. Publications in peer-reviewed journals or conference proceedings (NeurIPS, ICML, KDD) belong in a separate Publications section and can be a meaningful differentiator at research-oriented companies.
- Include thesis title if it is directly relevant to the role
- Kaggle: list tier (Expert, Master, Grandmaster) and top competition finish
- Publications: Author(s), title, venue, year — use a condensed citation format
Mistakes to avoid
- Listing tools without context — writing 'Python, TensorFlow, SQL' in a skills section without showing where and how you used them tells a recruiter nothing about your actual proficiency level.
- Describing model performance only in technical metrics (AUC, RMSE, F1) without translating those numbers into a business outcome, which makes it impossible for a non-technical hiring manager to gauge your impact.
- Omitting the deployment or production status of your models, leaving reviewers unsure whether your work influenced real decisions or stayed in a Jupyter notebook.
- Using a visually complex template with sidebars, progress-bar skill ratings, and embedded charts, which frequently breaks ATS parsing and causes your resume to be scored as nearly blank.
Frequently asked questions
- Should a Data Scientist resume include a GitHub link?
- Yes, if your repositories are clean and documented. A GitHub profile with well-structured projects — clear README files, reproducible code, and a stated business or research problem — functions as a second portfolio and is actively checked by technical hiring managers. Remove or privatize any repositories that contain messy, uncommented code, because a poor GitHub profile can hurt you more than having none at all.
- How important is a master's degree for a Data Scientist resume?
- It depends heavily on the employer. Research-oriented roles at tech giants, hedge funds, and pharmaceutical companies often list a master's or PhD as a hard requirement. Product-focused or startup roles weight demonstrated skills, shipped projects, and certifications more heavily than credentials. If you lack a graduate degree, a strong portfolio, relevant certifications, and quantified work experience can close most of that gap.
- How do you handle a Data Scientist resume when your models never reached production?
- Be specific about the stage the work reached and the analytical value it produced — for example, 'developed and validated a demand-forecasting model in a staging environment; findings adopted by the supply chain team to adjust safety-stock thresholds.' Framing the impact on decisions or processes, even when full deployment did not happen, shows business awareness. Avoid claiming production deployment if it did not occur, because technical interviewers will ask detailed questions about infrastructure that will expose the gap.
Make it yours in minutes
Open this example in the builder, swap in your details, and export a clean, ATS-ready resume.
Once your resume is ready
More for this application
- Cover letter example
- Data Scientist Cover Letter Example
- Template style
- Professional resume templates